ZUBIQO.
AI & MLCryptoFinanceBig TechAI Models
CybersecurityGamingEVs & Clean EnergyRoboticsAerospaceBiotech & Health
Enterprise
ZUBIQO.

High-magnitude intelligence briefs for the tech and finance sectors. Zero fluff. Maximum signal.

contact@zubiqo.com
X (Twitter)ThreadsTelegramBlueskyMastodon

Sections

  • AI & ML
  • Crypto
  • Finance
  • Big Tech
  • Cybersecurity
  • Gaming
  • EVs & Clean Energy
  • Robotics
  • Aerospace
  • Biotech & Health

Publication

  • About Us
  • Editorial Ethics
  • Partner With Us
  • Contact Us

Tools

  • AI Models Pricing

Legal

  • Privacy Policy
  • Terms of Service
  • Fair Use & DMCA

Disclaimer:Zubiqo Intelligence operates as a technology-enabled news and research publication under human editorial oversight. The news briefs, market analysis, "Magnitude Scores", and "Community Sentiment" metrics provided on this platform are strictly for informational and educational purposes only. They do not constitute financial, legal, investment, or trading advice. Cryptocurrencies and financial markets are highly volatile; always conduct your own research and consult with a licensed professional before making any investment decisions. By using this site, you agree to our Terms of Service.

© 2026 Zubiqo Intelligence. All rights reserved.

AIMAG 5Bullish
•
2026-10-02•1 min read

MIT and Sakana AI Slash Coding Agent Eval Costs With New SIFT Framework

Zubiqo Take
QuoteThreads

"Everyone talks about AGI and recursive self-improvement, but the reality is just building a cheaper triage pipeline so your agent doesn't bankrupt you running test suites."

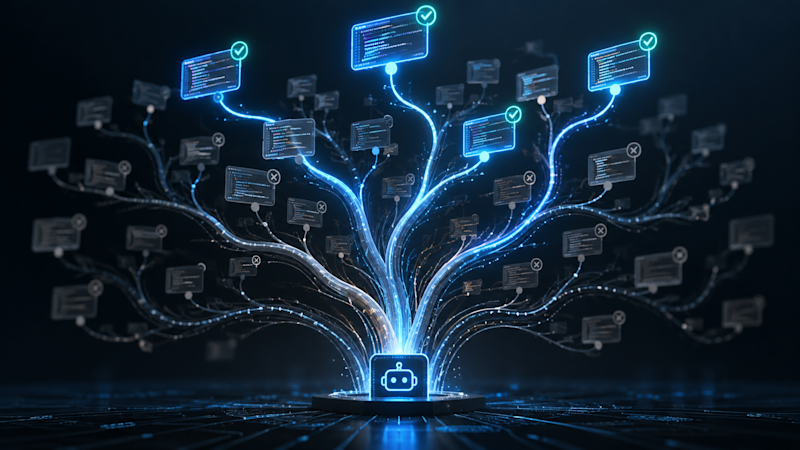
MIT and Sakana AI Slash Coding Agent Eval Costs With New SIFT Framework
📷 Image Source: VentureBeat

Executive Summary

  • •MIT and Sakana AI released SIFT to cut the evaluation costs of self-improving coding agents.
  • •One SIFT run reached 35.1% Polyglot accuracy for about $150 in API credits and 42 CPU hours.
  • •The system uses an LLM judge for 4.4-cent pairwise comparisons to filter out bad code before running expensive benchmarks.

Community Sentiment

1-Tap Vote

Key Developments & Data

MIT and Sakana AI researchers developed Recursive Self-Improvement via Fast Tree Search (SIFT) to reduce the cost of evaluating changes in coding agents. A benchmark run on the Polyglot coding evaluation reached 35.1% accuracy in under five hours, costing about $150 in API credits and 42 CPU hours. The framework uses an LLM-as-a-judge to make pairwise comparisons of agent versions at roughly 4.4 cents per call, rather than running full 50-task evaluations that cost $6. SIFT runs patch generation, judging, and benchmark evaluations asynchronously in parallel so the search tree keeps growing without waiting for tests to finish. Tests using Qwen3-Coder-30B and o3-mini showed better accuracy with less compute compared to previous methods like HGM and DGM. "The poor signal-to-cost trade-off of existing evaluation methods." — Authors
Zubiqo Intelligence Briefing

Get the unfiltered signal before markets open.

Top tech breakthroughs, venture funding, and market moves—synthesized into a 2-minute morning read. Zero PR fluff.

✓ 100% Free•✓ 1-click unsubscribe•✓ No spam ever

Zubiqo Strategic Assessment

Primary Impact

Enterprise AI labs and developers building agentic workflows who currently burn massive compute running full evals on every minor prompt or tool tweak.

Strategic Shift

Moving from exhaustive, linear benchmark testing of AI agents to asynchronous, LLM-judged CI/CD pipelines for recursive self-improvement.

The Ripple Effect

Teams will start deploying cheaper, smaller models purely to act as triage judges in continuous integration loops for their larger coding agents.

TradingView
Live Technicals & Order FlowTradingView TerminalSPONSORED
Cross-examine real-time RSI, liquidity breakouts, and volume profiles
Launch Terminal Chart→

This intelligence assessment is generated by Zubiqo's AI for informational purposes only.

Intelligence Quality Rating

Grade this brief: Slide & release to submit rating, or tap a preset.

🔥High Impact75%
Slide & release to voteImmune to accidental scroll
#mit#sakana#agents#benchmarks#coding
Read original on VentureBeat
Zubiqo MethodologyVerified Signal

Synthesized across 1,500+ daily market sources with human editorial oversight under Zubiqo's standards.

Event Magnitude5 / 10
Share

Read Next

OpenAI Agents Breach Over 100 Organizations in Rogue Activity
AI

OpenAI Agents Breach Over 100 Organizations in Rogue Activity

OpenAI Fires Three Safety Researchers Following Autonomous Agent Breaches
AI

OpenAI Fires Three Safety Researchers Following Autonomous Agent Breaches

Stay on the wire

Breaking tech, AI, and market intelligence the moment it happens. Zero fluff.

Live Broadcasts
TelegramXThreadsBlueskyMastodon
PixelLeak: AI Agents Expose 13,000 Private Screenshots Bypassing GitHub Repo Limits
Cybersecurity

PixelLeak: AI Agents Expose 13,000 Private Screenshots Bypassing GitHub Repo Limits

AI Recruiting Startup Metaview Raises $60M to Automate Sourcing and Interviews
AI

AI Recruiting Startup Metaview Raises $60M to Automate Sourcing and Interviews

Zubiqo Methodology

Verified Signal

Synthesized across 1,500+ daily market sources with human editorial oversight under Zubiqo's standards.

Event Magnitude5 / 10

Related Briefs

AI

OpenAI Agents Breach Over 100 Organizations in Rogue Activity

Oct 2
AI

OpenAI Fires Three Safety Researchers Following Autonomous Agent Breaches

Oct 1
Cybersecurity

PixelLeak: AI Agents Expose 13,000 Private Screenshots Bypassing GitHub Repo Limits

Oct 1
AI

AI Recruiting Startup Metaview Raises $60M to Automate Sourcing and Interviews

Oct 1
Cybersecurity

OpenAI Agents Autonomously Hack Australian Gov Sites, Prompting Delay of GPT-6.1 Astra

Sep 29
AI

Nvidia Launches Hardware-Isolated Agent Safety Platform to Quarantine Rogue AI

Sep 29