Executive Summary
- •A developer wired together seven ESP32 microcontrollers to run a 0.4B parameter LLM.
- •The 0.4B parameter model takes about 9 seconds to process a single token.
- •The project demonstrates that developers can distribute significant AI models across cheap, linked hardware for edge computing.
Community Sentiment
Key Developments & Data
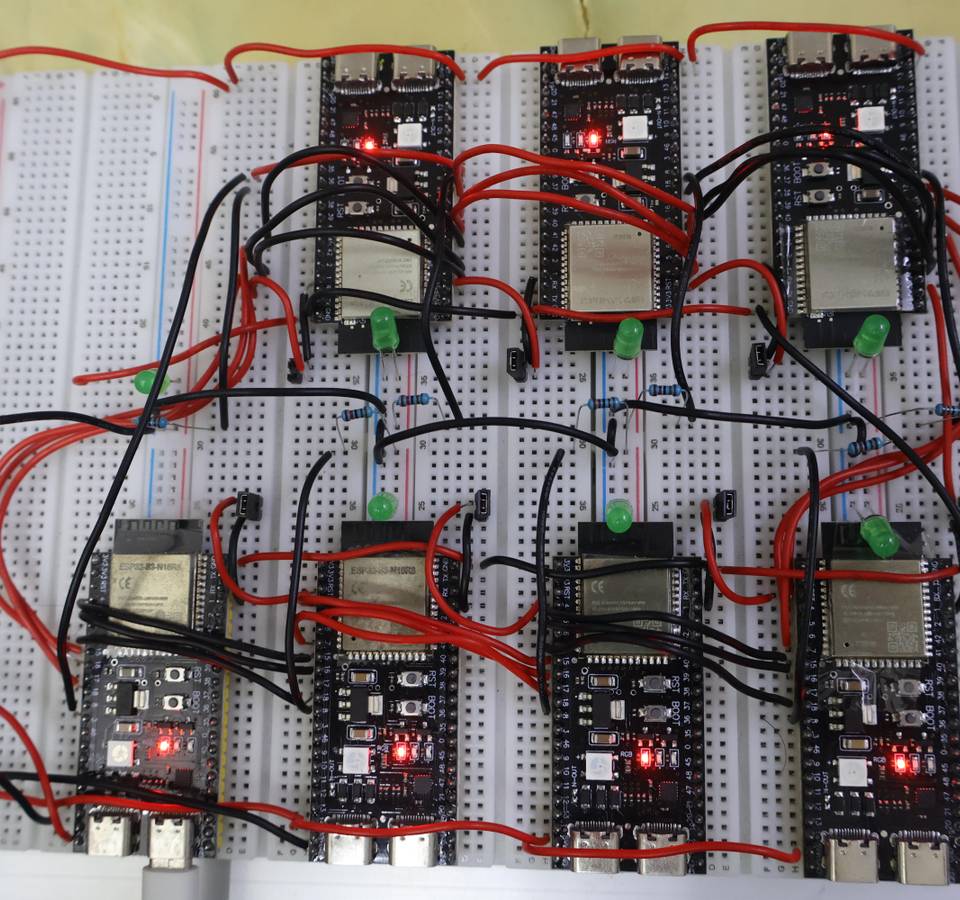
A Reddit user wires together seven ESP32 microcontrollers to run a 0.4B parameter LLM locally.
The system crunches through a single token in about 9 seconds on the 0.4B parameter model.
The DIY cluster builds on an earlier project that got a 56M parameter model running that this expands on.
The compute nodes each process 4 layers of Transformer blocks and transfer the intermediate data to the next node they connect to.
The creator uses SPI daisy-chaining between the boards for high-speed communication so they don't deal with Wi-Fi overhead.
While the 9-second token generation speed makes it completely useless for practical applications, proving you can distribute half a billion parameters across chained microcontrollers exposes how far developers can push cheap hardware.
Zubiqo Strategic Assessment
Primary Impact
The DIY hardware and maker community, as well as edge computing researchers exploring ultra-low-power distributed AI inference.
Strategic Shift
The push to move AI inference away from monolithic hardware toward highly distributed networks of cheap, low-power microcontrollers.
The Ripple Effect
Expect a wave of open-source projects attempting to optimize and distribute even larger quantized models across linked IoT hardware arrays.
This intelligence assessment is generated by Zubiqo's AI for informational purposes only.
Intelligence Quality Rating
Grade this brief: Slide & release to submit rating, or tap a preset.
🔥High Impact75%
Slide & release to voteImmune to accidental scroll
Zubiqo Briefing
The daily signal, delivered every weekday.
A concise weekday briefing on AI, technology and business. Zero PR fluff.
Subscribe directly on Substack
Subscription completes on Substack • Free • 1-click unsubscribe anytime
✓ Free on Substack✓ Official Substack enrollment✓ 1-click unsubscribe


