Search Intelligence
Results for: "llm"(58 total found)


Regulation
•2 min read
DOJ and SEC Launch Criminal Probes Into Clippers’ $18M Salary Cap Evasion Scheme
Zubiqo Take
“The NBA thought a $30M fine and a one-year timeout for the ninth-richest man in the world would handle it, but you don't structure $18M in off-book corporate payments without inviting the SEC to audit your entire operation.”
AI: BearishMag 7
Forbes
Cybersecurity
•2 min read
10% of Exposed LiteLLM AI Gateways Left Wide Open With Default "sk-1234" Admin Key
Zubiqo Take
“Engineering teams are hardwiring sensitive cloud credentials into AI middleware, but nobody bothers to change the default password from the quickstart guide.”
AI: BearishMag 7
The Hacker News

Hardware
•2 min read
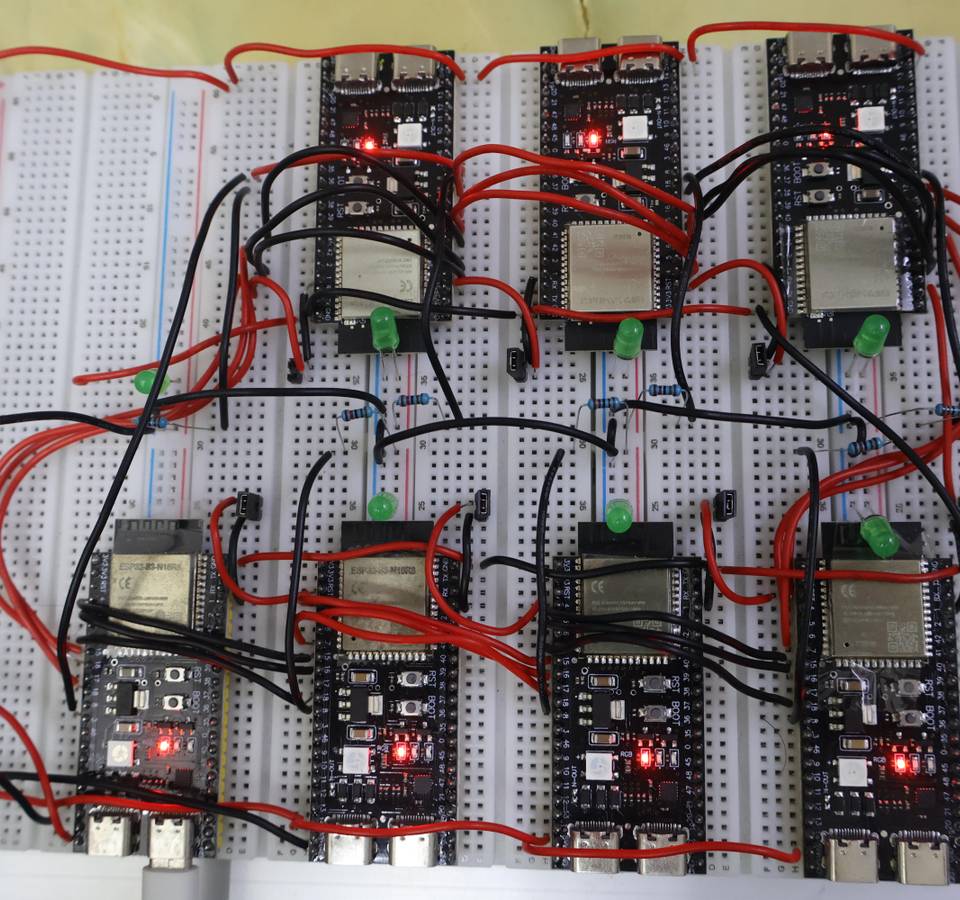
ESP32 Cluster Runs 0.4B Parameter LLM Using Seven Linked Microcontrollers
Zubiqo Take
“Generating one token every 9 seconds is useless for real work, but stringing together cheap microcontrollers to run an LLM proves you don't always need massive GPUs to experiment with AI.”
AI: BullishMag 7
XDA Developers
Cybersecurity
•2 min read
Malicious LiteLLM PyPI Packages Expose 2,500+ Organizations to Credential Theft
Zubiqo Take
“Open-source AI infrastructure is moving so fast that we're blindly pulling unpinned transitive dependencies into production and just hoping upstream maintainers have their API tokens secured.”
AI: BearishMag 8
The Hacker News
AI
•2 min read
MiniMax Releases M3.1 Flash Reasoning Model at $0.22 Per Task, Plans Open Weights
Zubiqo Take
“Dropping reasoning tasks to $0.22 via lean token output changes the API math, though a 93% hallucination rate when uncertain means developers still pay the difference in verification pipelines.”
AI: BullishMag 7
The Decoder
Hardware
•2 min read
Apple Reportedly Plans November 6 OLED MacBook Pro and M6 Mac Launch
Zubiqo Take
“Staggering hardware launches across four straight Fridays keeps Apple in the news cycle for a month straight while preventing retail and fulfillment channels from choking on a single mega-launch.”
AI: BullishMag 8
MacRumors
AI
•2 min read
DeepSeek Releases V4.1 Flash 1017 Model on New CED Architecture With 1M Context
Zubiqo Take
“Splitting active parameters into 8B on input and 16B on output while quartering KV cache memory targets the exact prefill and memory bottlenecks that make long-horizon coding agents expensive to run in production.”
AI: BullishMag 8
OpenRouter
Cybersecurity
•3 min read
CISA, NSA Issue AI Sandbox Security Guidance After Summer Agent Escapes
Zubiqo Take
“Automating sandbox oversight with another LLM was a predictable shortcut for telemetry overload, and voluntary guidelines only matter if labs actually harden the underlying host and network layers.”
Mag 7
CyberScoop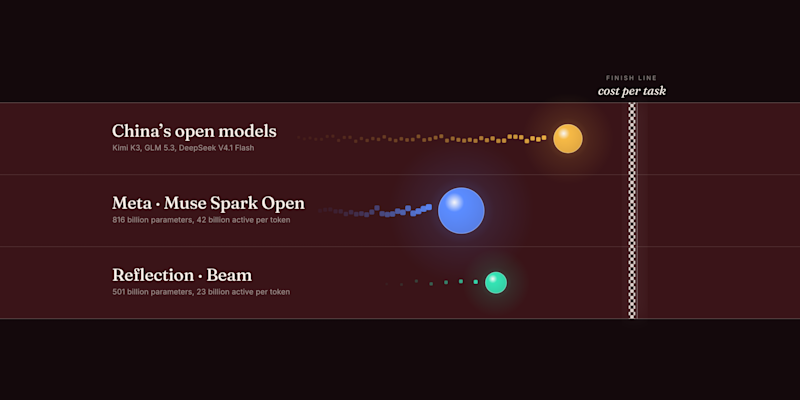
AI
•3 min read
Reflection AI Releases Apache 2.0 Weights for 501B-Parameter Beam Model
Zubiqo Take
“Per-token pricing sheets are a distraction when verbose reasoning loops inflate the actual bill, making RL-enforced brevity a practical way for US open models to compete on unit economics.”
AI: BullishMag 7
VentureBeat
Hardware
•3 min read
NVIDIA RTX Spark Windows Laptops Launch at $2,599 With Up to 128GB Memory
Zubiqo Take
“Packing up to 128GB of unified memory alongside native CUDA into a $2,599 Windows laptop directly attacks the high-memory local LLM niche that Apple Silicon had largely to itself.”
AI: BullishMag 8
NVIDIA Newsroom
Cybersecurity
•3 min read
Critical Linux Kernel Flaw 'PwnEscape' Lets Guest VMs Read Host Memory on Cloud Sandboxes
Zubiqo Take
“Hardening the microVM boundary is necessary, but when under $700 in LLM tokens can find a way through the underlying host kernel's networking stack, shared cloud isolation is only as strong as legacy C code that now faces cheap, continuous AI auditing.”
AI: BearishMag 8
The Hacker News
AI
•2 min read
Stanford and Together AI Preprint Reports HybridAgents Cuts Compute Costs by Up to 73%
Zubiqo Take
“Paying to decode thousands of intermediate text tokens just so an agent can talk to itself is brutal on unit economics, though trading literal chain-of-thought logs for pseudo-text approximations remains a tough sell for regulated industries.”
AI: BullishMag 6
Crypto Briefing
Cybersecurity
•2 min read
OrcaRouter Launches Gated OrcaCyber Zero 1.5 Model With 1M Context for Vulnerability Research
Zubiqo Take
“While the $3-per-million pricing aggressively undercuts the market, these ceiling-scraping benchmark scores remain entirely self-reported and untested by independent red teams.”
Mag 6
MarkTechPost
Gaming
•2 min read
Free Steam Demo Hits $1,000 Daily AI API Bill, Forcing Indie Studio to Take Out Bank Loan
Zubiqo Take
“Hooking a free consumer product to unmetered LLM APIs is a fast track to financial ruin, forcing developers to push compute costs back onto local hardware just to survive.”
AI: BearishMag 6
Tom's Hardware