ZUBIQO.
AI & MLCryptoFinanceBig TechAI Models
CybersecurityGamingEVs & Clean EnergyRoboticsAerospaceBiotech & HealthConsumer Hardware
Enterprise
ZUBIQO.

High-magnitude intelligence briefs for the tech and finance sectors. Zero fluff. Maximum signal.

contact@zubiqo.com
X (Twitter)ThreadsTelegramBlueskyMastodon

Sections

  • AI & ML
  • Crypto
  • Finance
  • Big Tech
  • Cybersecurity
  • Gaming
  • EVs & Clean Energy
  • Robotics
  • Aerospace
  • Biotech & Health

Topics

  • OpenAI
  • Anthropic
  • Nvidia
  • Apple
  • Google
  • Microsoft
  • Meta
  • Tesla
  • SpaceX
  • Amazon
  • DeepSeek
  • Bitcoin

Publication

  • Evening Newsletter
  • About Us
  • Editorial Ethics
  • Partner With Us
  • Contact Us

Tools

  • AI Models Pricing

Legal

  • Privacy Policy
  • Terms of Service
  • Fair Use & DMCA

Disclaimer:Zubiqo Intelligence is a technology and market news publication; briefs are AI-assisted and link to their original sources. The news briefs, market analysis, “Magnitude Scores”, and “Community Sentiment” metrics provided on this platform are strictly for informational and educational purposes only. They do not constitute financial, legal, investment, or trading advice. Cryptocurrencies and financial markets are highly volatile; always conduct your own research and consult with a licensed professional before making any investment decisions. By using this site, you agree to our Terms of Service.

© 2026 Zubiqo Intelligence. All rights reserved.

  1. Home
  2. /
  3. AI
  4. /
  5. NVIDIA Releases Open Nemotron 3.5 Bolt E4B Model for Local Edge Agents
AIMAG 6Bullish

NVIDIA Releases Open Nemotron 3.5 Bolt E4B Model for Local Edge Agents

Zubiqo Brief•via MarkTechPost•2026-10-24•3 min read
NVIDIA Releases Open Nemotron 3.5 Bolt E4B Model for Local Edge Agents
📷 Image Source: MarkTechPost

Executive Summary

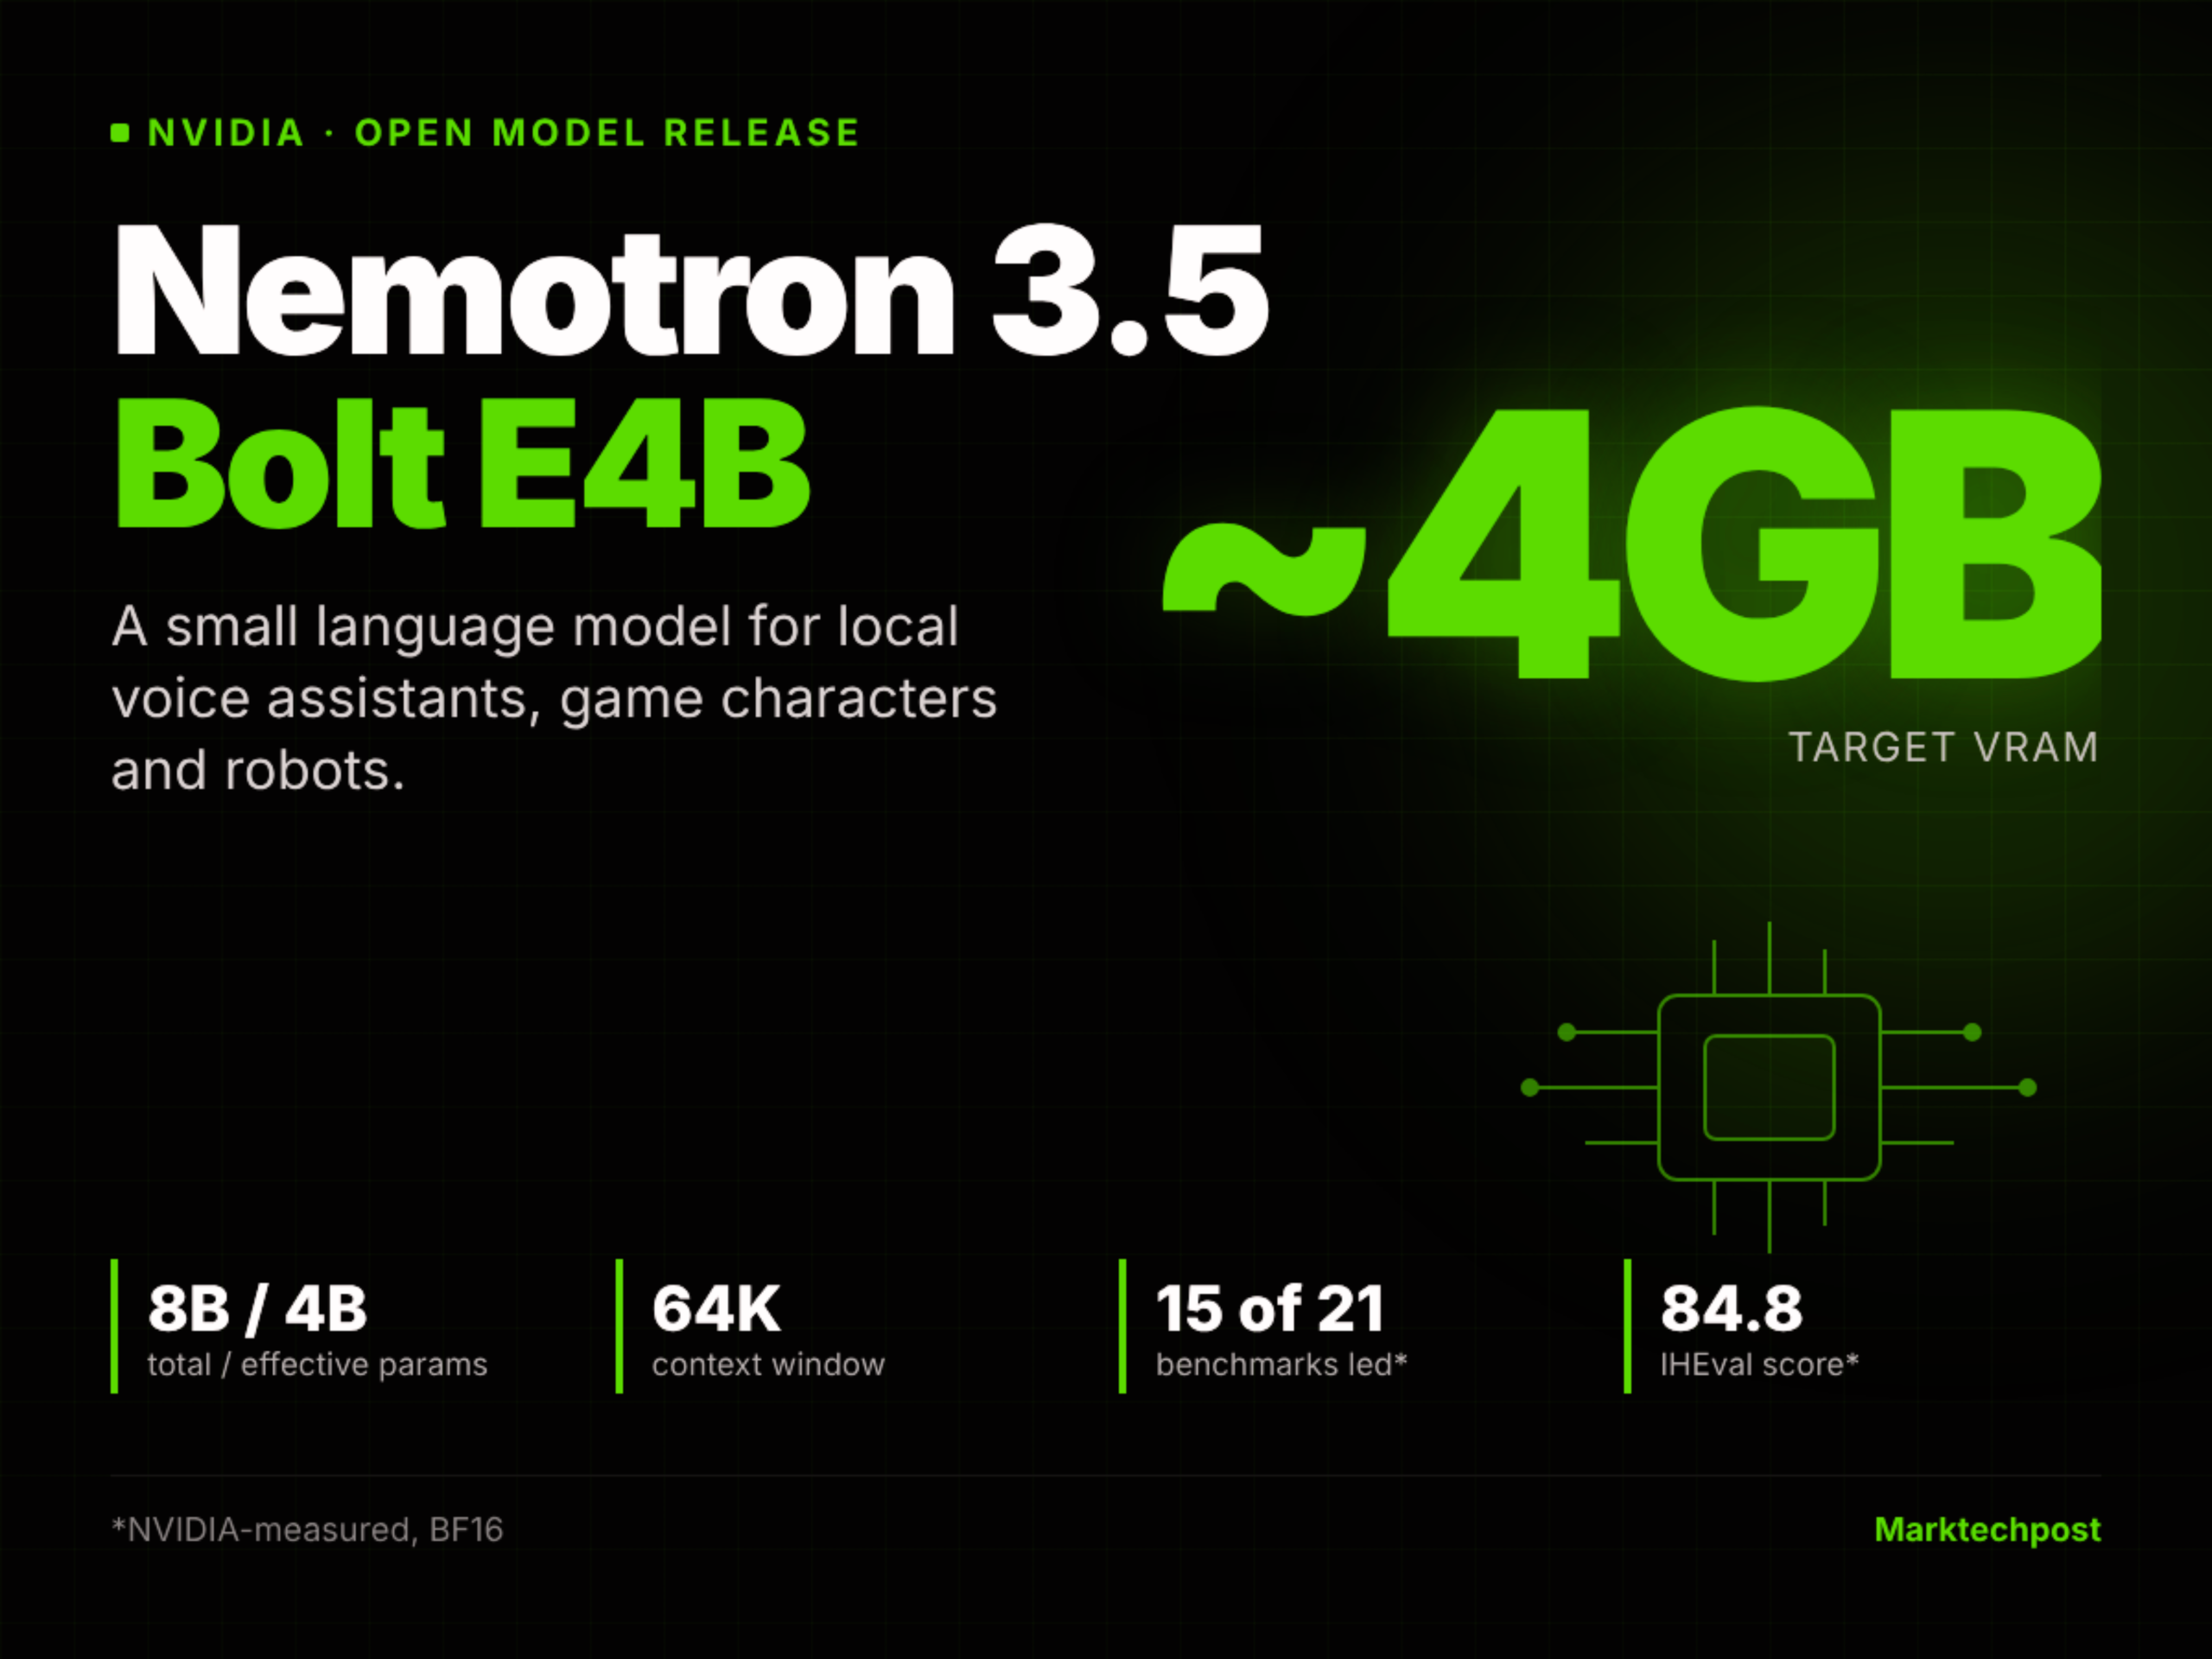
  • •NVIDIA released Nemotron 3.5 Bolt E4B 4GB, an open small language model post-trained from Google's Gemma 4 E4B using reinforcement learning for local voice agents, game characters, and robots.
  • •The Q4_K_M build uses 3.1 to 4.3 GB of VRAM on RTX hardware, hits 272.6 tokens/s on an RTX 5070, and led 15 of 21 benchmarks in NVIDIA's internal harness.
  • •Open weights, training datasets, and recipes are available under the OpenMDW-1.1 license to run locally alongside vision and speech models on RTX, Jetson, and Spark devices.

Zubiqo Take

QuoteThreads

Calling a 6.18 GB GGUF file a "4GB" model is classic marketing math, even if keeping runtime VRAM under 4.3 GB genuinely leaves room for local voice and vision models on consumer RTX cards.

Key Developments & Data

NVIDIA released Nemotron 3.5 Bolt E4B 4GB, an open small language model with 8B total parameters, 4B effective parameters, and a 64K context window designed for local voice assistants, game NPCs, and robot interfaces. Post-trained from Google's Gemma 4 E4B using strictly reinforcement learning (RLVR and RLHF via NeMo-RL and NeMo-Gym) without supervised fine-tuning, the Q4_K_M quantized build consumed 3.1 to 4.3 GB of VRAM on RTX hardware during NVIDIA's testing, despite a 6.18 GB GGUF file size on Hugging Face. Equipped with a DFlash drafter for speculative decoding, Bolt reached 272.6 tokens/s on an RTX 5070—1.21x faster than Gemma 4 E4B's 225.9 tokens/s—while claiming up to 80% fewer output tokens in reasoning-enabled comparisons and roughly 40% higher average scores than Nemotron 3 Nano 4B. In NVIDIA's internal NeMo-Gym harness, the BF16 model led 15 of 21 benchmarks against Gemma 4 E4B, Qwen3.5-4B, and Nemotron 3 Nano 4B, peaking at 84.8 on IHEval, though Qwen3.5-4B beat it on Tau2-Bench (75.1 vs 55.1), RULER 64K (95.1 vs 87.0), LongBench v2 (59.9 vs 50.5), and BFCL-v3 (70.9 vs 68.5). The open weights, datasets, and training recipes are available under the OpenMDW-1.1 license across Hugging Face, Ollama, LM Studio, Unsloth, Jetson AI Lab, NVIDIA NIM, and the In-Game Inferencing SDK.

Zubiqo Strategic Assessment

Primary Impact

Game developers using NVIDIA ACE, robotics engineers deploying on Jetson Orin Nano boards, and local AI developers building edge voice agents on GeForce RTX and Spark hardware.

Strategic Shift

Post-training small base models strictly with reinforcement learning and length penalties to preserve conversational brevity while adding multi-turn tool calling within tight edge VRAM budgets.

The Ripple Effect

Keeping the conversational agent footprint between 3.1 and 4.3 GB of VRAM allows developers to co-locate vision and speech models like Cosmos 3 Edge on a single 8GB edge device or consumer GPU without offloading to cloud APIs.

TradingView
Live Technicals & Order FlowTradingView TerminalAFFILIATE PARTNER
Cross-examine real-time RSI, liquidity breakouts, and volume profiles
Launch Terminal Chart→
Affiliate disclosure: We may earn a commission if you subscribe to TradingView through this link.

This intelligence assessment is generated by Zubiqo's AI for informational purposes only.

Community Sentiment

1-Tap Vote
Zubiqo Briefing

The daily signal, delivered every weekday.

A concise weekday briefing on AI, technology and business. Zero PR fluff.

Subscribe directly on Substack↗

Subscription completes on Substack • Free • 1-click unsubscribe anytime

✓ Free on Substack•✓ Official Substack enrollment•✓ 1-click unsubscribe

Intelligence Quality Rating

Grade this brief: Slide & release to submit rating, or tap a preset.
🔥High Impact75/100
Slide & release to voteImmune to accidental scroll
#nvidia#nemotron#gemma#local ai#open weights
More Nvidia news →Read original on MarkTechPost
Zubiqo MethodologySource-linked

AI-assisted brief based on the original reporting linked below, published under Zubiqo's editorial standards. Have a correction? Contact our desk.

Event Magnitude6 / 10
Share

Read Next

SpaceX Struggles to Finalize $40B Debt Deal for Nvidia AI Chips, Bloomberg Reports
Aerospace/Space

SpaceX Struggles to Finalize $40B Debt Deal for Nvidia AI Chips, Bloomberg Reports

AI

Nvidia CEO Jensen Huang Backs Kazakhstan AI Push as Firebird Inks GPU Deal

Stay on the wire

Breaking tech, AI, and market intelligence the moment it happens. Zero fluff.

Live Broadcasts
TelegramXThreadsBlueskyMastodon
Export-Restricted Nvidia B300 GPUs Discovered Inside China Telecom Network
Hardware

Export-Restricted Nvidia B300 GPUs Discovered Inside China Telecom Network

Nvidia Launches Minerva AIOps Platform to Monitor Massive AI Clusters
Big Tech

Nvidia Launches Minerva AIOps Platform to Monitor Massive AI Clusters

Zubiqo Methodology

Source-linked

AI-assisted brief based on the original reporting linked below, published under Zubiqo's editorial standards. Have a correction? Contact our desk.

Event Magnitude6 / 10

Related Briefs

Aerospace/Space

SpaceX Struggles to Finalize $40B Debt Deal for Nvidia AI Chips, Bloomberg Reports

Oct 24
AI

Nvidia CEO Jensen Huang Backs Kazakhstan AI Push as Firebird Inks GPU Deal

Oct 24
Hardware

Export-Restricted Nvidia B300 GPUs Discovered Inside China Telecom Network

Oct 23
Big Tech

Nvidia Launches Minerva AIOps Platform to Monitor Massive AI Clusters

Oct 23
AI

Nvidia and TCV Invest in AI Video Startup Higgsfield in Series B Extension

Oct 23
Big Tech

Infineon and NVIDIA Expand 800V DC GaN Power Collaboration for 1 MW AI Racks

Oct 23