Executive Summary
- •Prime Intellect launched a serving platform for frontier open models with serverless endpoints and reserved capacity.
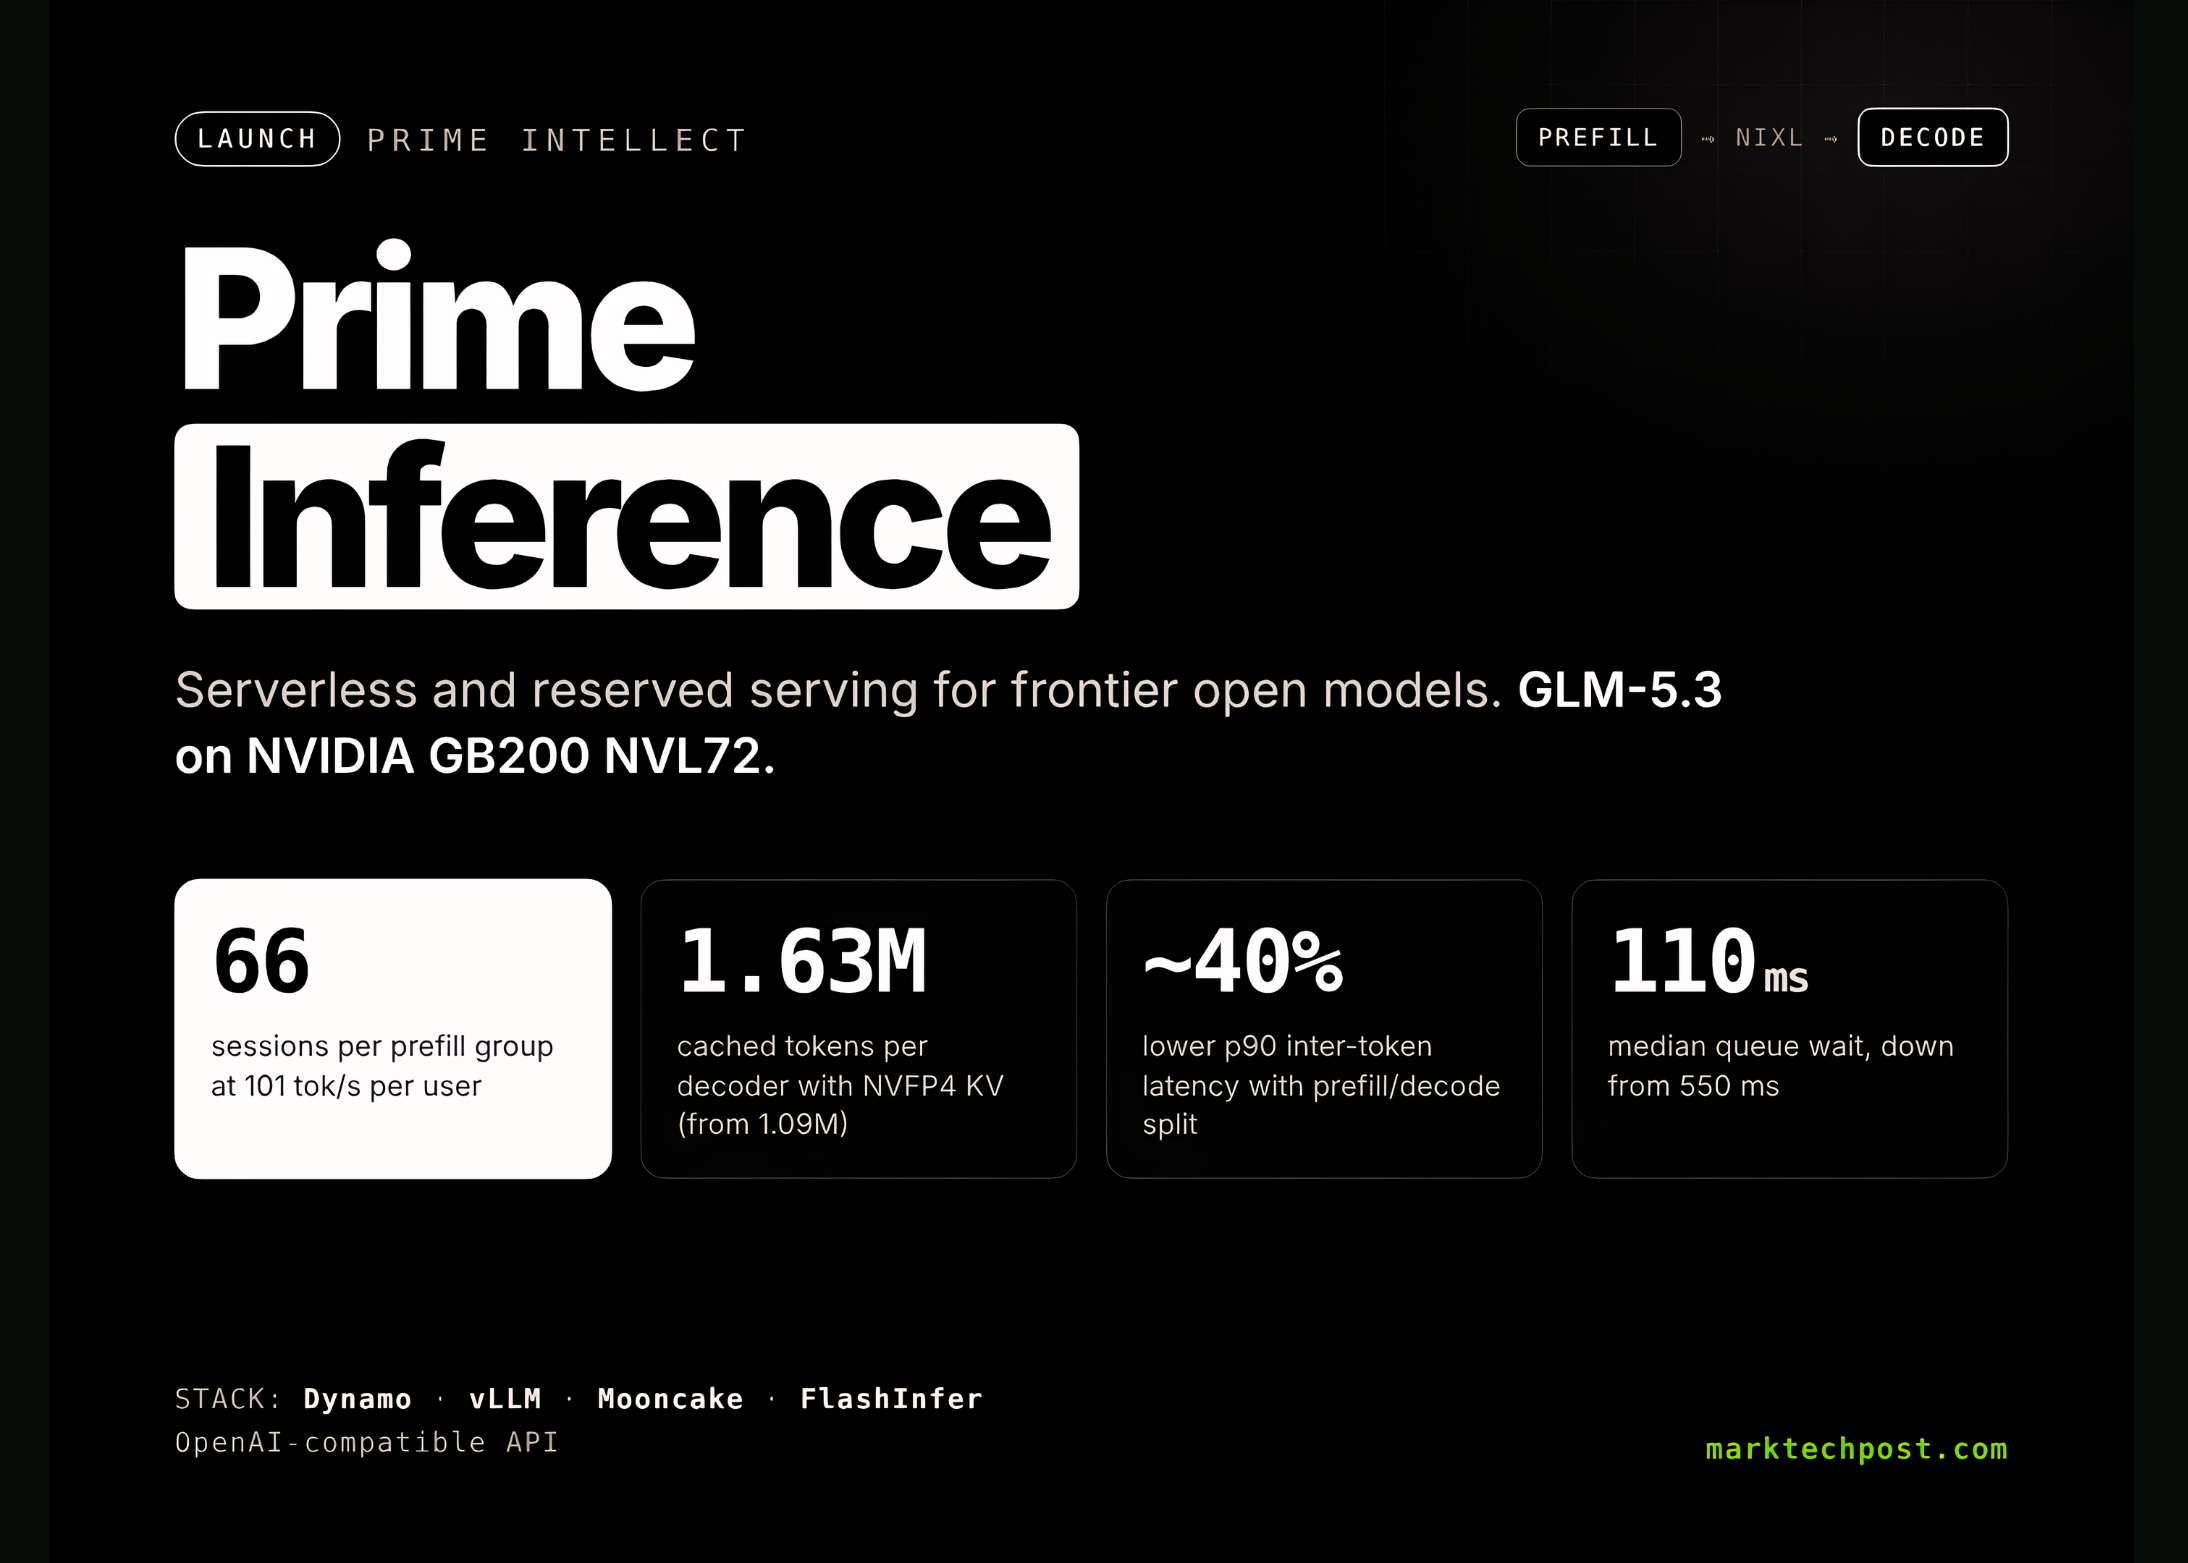
- •The system processed nearly a trillion tokens per day internally and achieved nearly 40% lower p90 inter-token latency.
- •Disaggregating prefill and decode across separate GPU groups allows them to efficiently handle massive agentic context windows.
Community Sentiment
Key Developments & Data
Prime Intellect rolled out Prime Inference to provide serverless endpoints and reserved capacity for open-source models across multiple datacenters.
The platform processed nearly a trillion tokens per day internally before its public release, driven by synthetic data generation and long-running coding agents.
The system achieved nearly 40% lower p90 inter-token latency because prefill and decode run on entirely separate GPU groups.
The routing stack weighs cached prefix overlap against queued work to keep sessions on the exact same decoder between turns.
Engineers contributed a structural-tag builder upstream to NVIDIA Dynamo and fixed underlying parsing bugs that agents depend on for accurate tool calls.
Zubiqo Intelligence Briefing
Get the unfiltered signal before markets open.
Top tech breakthroughs, venture funding, and market moves—synthesized into a 2-minute morning read. Zero PR fluff.
✓ 100% Free•✓ 1-click unsubscribe•✓ No spam ever
Zubiqo Strategic Assessment
Primary Impact
AI middleware and open-source inference providers face increased pressure as specialized, hardware-aware serving platforms optimize specifically for agentic workloads.
Strategic Shift
The transition from monolithic LLM serving to disaggregated prefill/decode architectures designed specifically for high-context agent sessions.
The Ripple Effect
More AI startups will likely fork or build custom serving layers on top of vLLM and NVIDIA Dynamo to stop massive token volume from crushing their compute margins.
This intelligence assessment is generated by Zubiqo's AI for informational purposes only.
Intelligence Quality Rating
Grade this brief: Slide & release to submit rating, or tap a preset.
🔥High Impact75%
Slide & release to voteImmune to accidental scroll